PyTorch basic operations
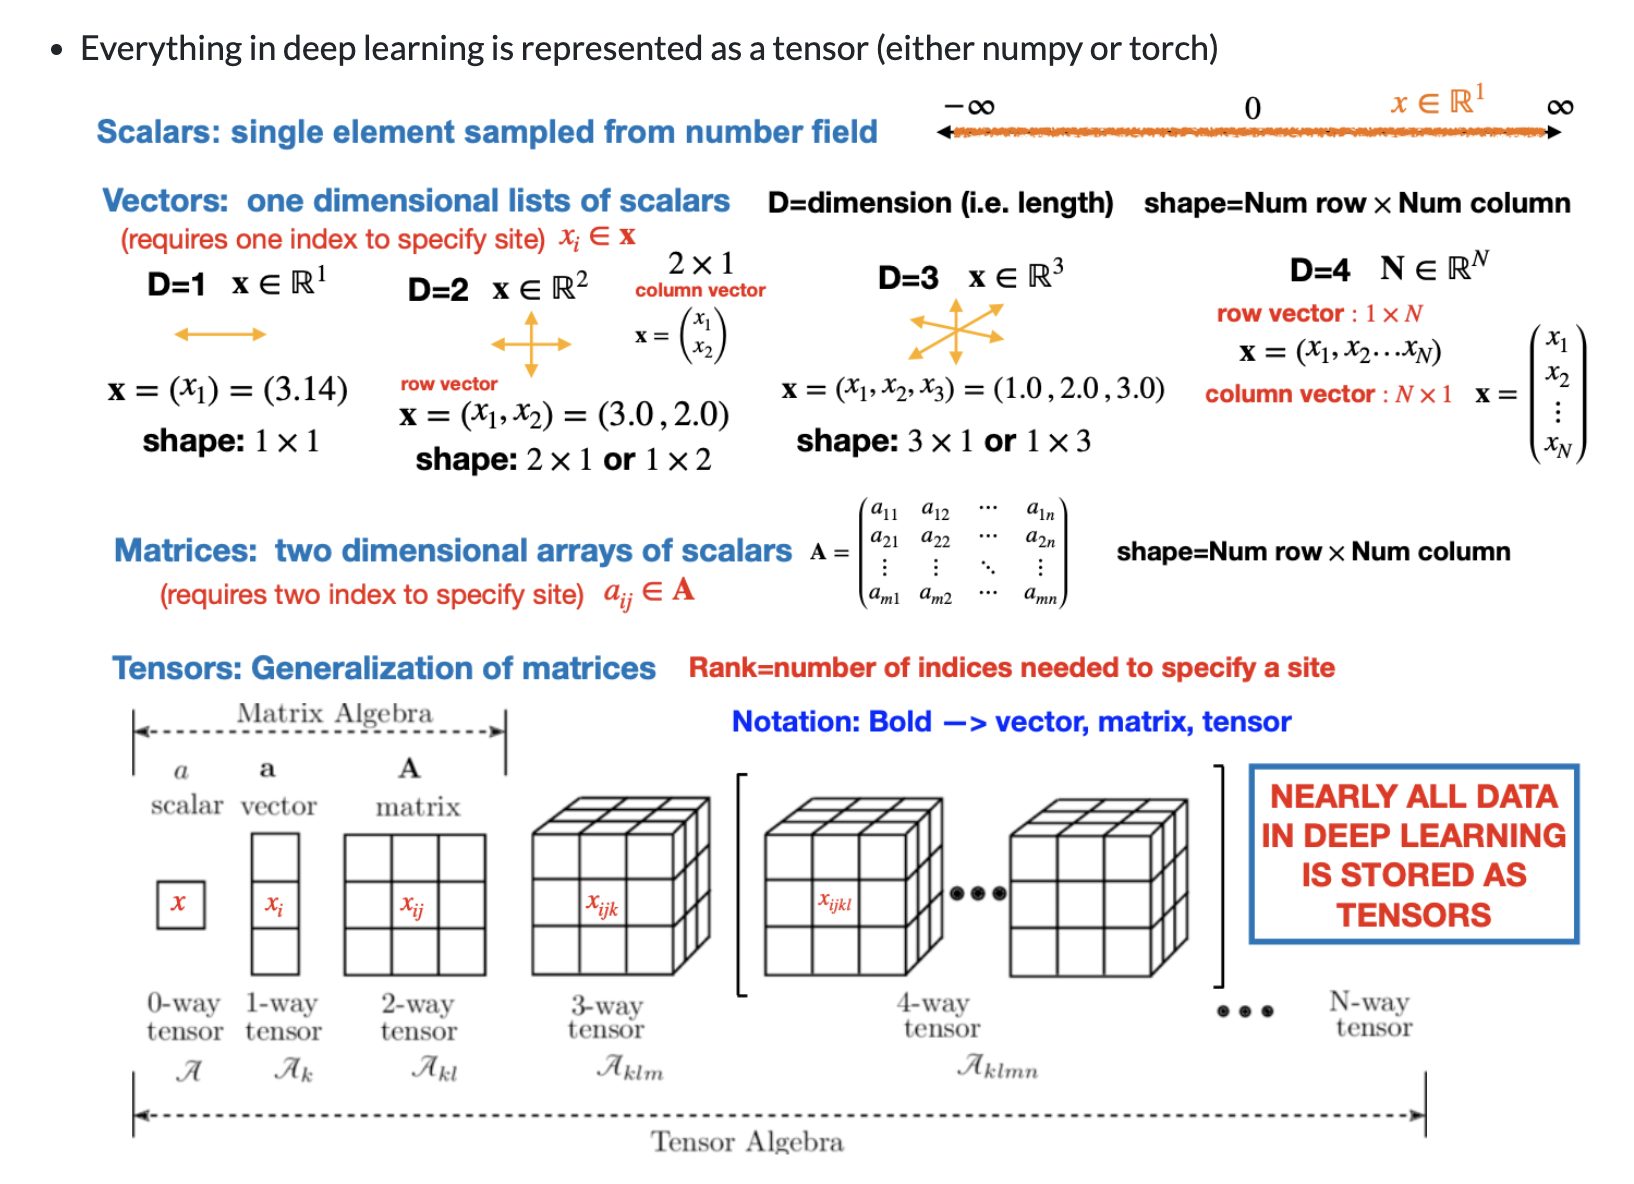
Tensors
Import
Numpy
Code
print("-------------------")
print("NUMPY EXAMPLE")
print("-------------------")
print("A:   ")
print(A)
print("A.T")
print(A.T)
print("A.shape  ",A.shape)
print("A[0,0]       ",A[0,0])
print("A[:,0]       ",A[:,0])
print("A[0,:]       ",A[0,:])
print("A[0,1:2]     ",A[0,1:2])
print("A[0,0].item()    ",A[0,0].item())
print("np.sin(A):       ")
print(np.sin(A))
-------------------
NUMPY EXAMPLE
-------------------
A:
[[11. 12. 13.]
[21. 22. 23.]]
A.T
[[11. 21.]
[12. 22.]
[13. 23.]]
A.shape (2, 3)
A[0,0] 11.0
A[:,0] [11. 21.]
A[0,:] [11. 12. 13.]
A[0,1:2] [12.]
A[0,0].item() 11.0
np.sin(A):
[[-0.99999021 -0.53657292 0.42016704]
[ 0.83665564 -0.00885131 -0.8462204 ]]PyTorch
Code
print("-------------------")
print("TORCH TENSOR EXAMPLE")
print("-------------------")
A=torch.tensor(A)   #CONVERT TO TORCH TENSOR
print("A:   ")
print(A)
print("A.shape  ",A.shape)
print("A[0,0]       "); print(A[0,0])
print("A[:,0]       "); print(A[:,0])
print("A[0,:]       "); print(A[0,:])
print("A[:,-1]      "); print(A[:,-1])
print("A.T")
print(A.T)
print("A[0,0].item()    ",A[0,0].item())
print("torch.sin(A):        ")
print("A device",A.device)
print("A dtype",A.dtype)
print("A is_contiguous",A.is_contiguous())
AT=A.T
print("A.T is_contiguous",AT.is_contiguous())
AT=AT.contiguous()
print("A.T is_contiguous",AT.is_contiguous())
print("A requires_grad",A.requires_grad)
A.requires_grad_(requires_grad=True)
print("A requires_grad",A.requires_grad)
print("A is cuda",A.is_cuda)
print("A.tolist ",A.tolist())
print("A.flatten()"); print(A.flatten())
print(torch.sin(A))
print(A.sin())
-------------------
TORCH TENSOR EXAMPLE
-------------------
A:
tensor([[11., 12., 13.],
[21., 22., 23.]], dtype=torch.float64)
A.shape torch.Size([2, 3])
A[0,0]
tensor(11., dtype=torch.float64)
A[:,0]
tensor([11., 21.], dtype=torch.float64)
A[0,:]
tensor([11., 12., 13.], dtype=torch.float64)
A[:,-1]
tensor([13., 23.], dtype=torch.float64)
A.T
tensor([[11., 21.],
[12., 22.],
[13., 23.]], dtype=torch.float64)
A[0,0].item() 11.0
torch.sin(A):
A device cpu
A dtype torch.float64
A is_contiguous True
A.T is_contiguous False
A.T is_contiguous True
A requires_grad False
A requires_grad True
A is cuda False
A.tolist [[11.0, 12.0, 13.0], [21.0, 22.0, 23.0]]
A.flatten()
tensor([11., 12., 13., 21., 22., 23.], dtype=torch.float64,
grad_fn=<ViewBackward0>)
tensor([[-1.0000, -0.5366, 0.4202],
[ 0.8367, -0.0089, -0.8462]], dtype=torch.float64,
grad_fn=<SinBackward0>)
tensor([[-1.0000, -0.5366, 0.4202],
[ 0.8367, -0.0089, -0.8462]], dtype=torch.float64,
grad_fn=<SinBackward0>)Code
print("-------------------")
print("TENSORS VIEWS")
print("-------------------")
x=torch.arange(8)
print(x)
x1=x.view(4, 2)
print(x1,x1.view(4, 2).is_contiguous())
x1[0]=1  #CHANGES ORIGINAL
print(x.view(2, 2, 2),x.view(2,2, 2))
print(x.view(2, 2, 2).shape)

x = torch.tensor([[1], [2], [3]])
print(x,x.size())
print(x.expand(3, 4))
print(x.expand(3, 2))
# -1 means not changing the size of that dimension
print(x.expand(-1, 4))
-------------------
TENSORS VIEWS
-------------------
tensor([0, 1, 2, 3, 4, 5, 6, 7])
tensor([[0, 1],
[2, 3],
[4, 5],
[6, 7]]) True
tensor([[[1, 1],
[2, 3]],
[[4, 5],
[6, 7]]]) tensor([[[1, 1],
[2, 3]],
[[4, 5],
[6, 7]]])
torch.Size([2, 2, 2])
tensor([[1],
[2],
[3]]) torch.Size([3, 1])
tensor([[1, 1, 1, 1],
[2, 2, 2, 2],
[3, 3, 3, 3]])
tensor([[1, 1],
[2, 2],
[3, 3]])
tensor([[1, 1, 1, 1],
[2, 2, 2, 2],
[3, 3, 3, 3]])Code
tensor([[ 2.0141,  0.6339,  0.0137],
        [-1.1859,  0.1602,  1.3198],
        [-1.2987,  1.2941,  1.0677]])
tensor([-1.2987])
tensor([-1.1859,  1.2941])
tensor([2.0141, 0.1602, 1.0677])
tensor([0.6339, 1.3198])
tensor([0.0137])
(tensor([[ 2.0141],
        [-1.1859],
        [-1.2987]]), tensor([[0.6339],
        [0.1602],
        [1.2941]]), tensor([[0.0137],
        [1.3198],
        [1.0677]]))
Code
print("-------------------")
print("OPERATIONS")
print("-------------------")
A=torch.tensor([[11., 12, 13], [21,22,23]]);
B=torch.tensor([[11., 12, 13]]);
print(A.shape,B.shape)
print(A+1.5)
print("BROADCASTING:",A+B)
print(torch.sigmoid(A))
print(B.sigmoid())
print(A*B)
print(A**2.0)
print(A.tanh())
-------------------
OPERATIONS
-------------------
torch.Size([2, 3]) torch.Size([1, 3])
tensor([[12.5000, 13.5000, 14.5000],
[22.5000, 23.5000, 24.5000]])
BROADCASTING: tensor([[22., 24., 26.],
[32., 34., 36.]])
tensor([[1.0000, 1.0000, 1.0000],
[1.0000, 1.0000, 1.0000]])
tensor([[1.0000, 1.0000, 1.0000]])
tensor([[121., 144., 169.],
[231., 264., 299.]])
tensor([[121., 144., 169.],
[441., 484., 529.]])
tensor([[1., 1., 1.],
[1., 1., 1.]])Code
print("-------------------")
print("COMPUTE GRADIENT-1")
print("-------------------")
x = torch.tensor(
    [[1.,2.], [3., 4.]],
    requires_grad=True)
# FORWARD
y   = (2*x**3).sum();
# BACKWARD
y.backward();
print("AUTOGRAD:\n",x.grad);
print("EXPECTED:\n",6*x**2)

print("-------------------")
print("COMPUTE GRADIENT-2")
print("-------------------")

x = torch.tensor([[1.,2.], [3., 4.]],
    requires_grad=True)
y = x**3;    #FORWARD
y = 2*y;
y = y.sin()
y = y.sum()
y.backward() #BACKWARD
print("AUTOGRAD:\n",x.grad);
print("EXPECTED:\n",torch.cos(2*x**3)*6*x**2)
-------------------
COMPUTE GRADIENT-1
-------------------
AUTOGRAD:
tensor([[ 6., 24.],
[54., 96.]])
EXPECTED:
tensor([[ 6., 24.],
[54., 96.]], grad_fn=<MulBackward0>)
-------------------
COMPUTE GRADIENT-2
-------------------
AUTOGRAD:
tensor([[ -2.4969, -22.9838],
[-44.7827, -66.5180]])
EXPECTED:
tensor([[ -2.4969, -22.9838],
[-44.7827, -66.5180]], grad_fn=<MulBackward0>)